# Code completion
{ .image-clip .translate-20 }
{ .text-center .muted }
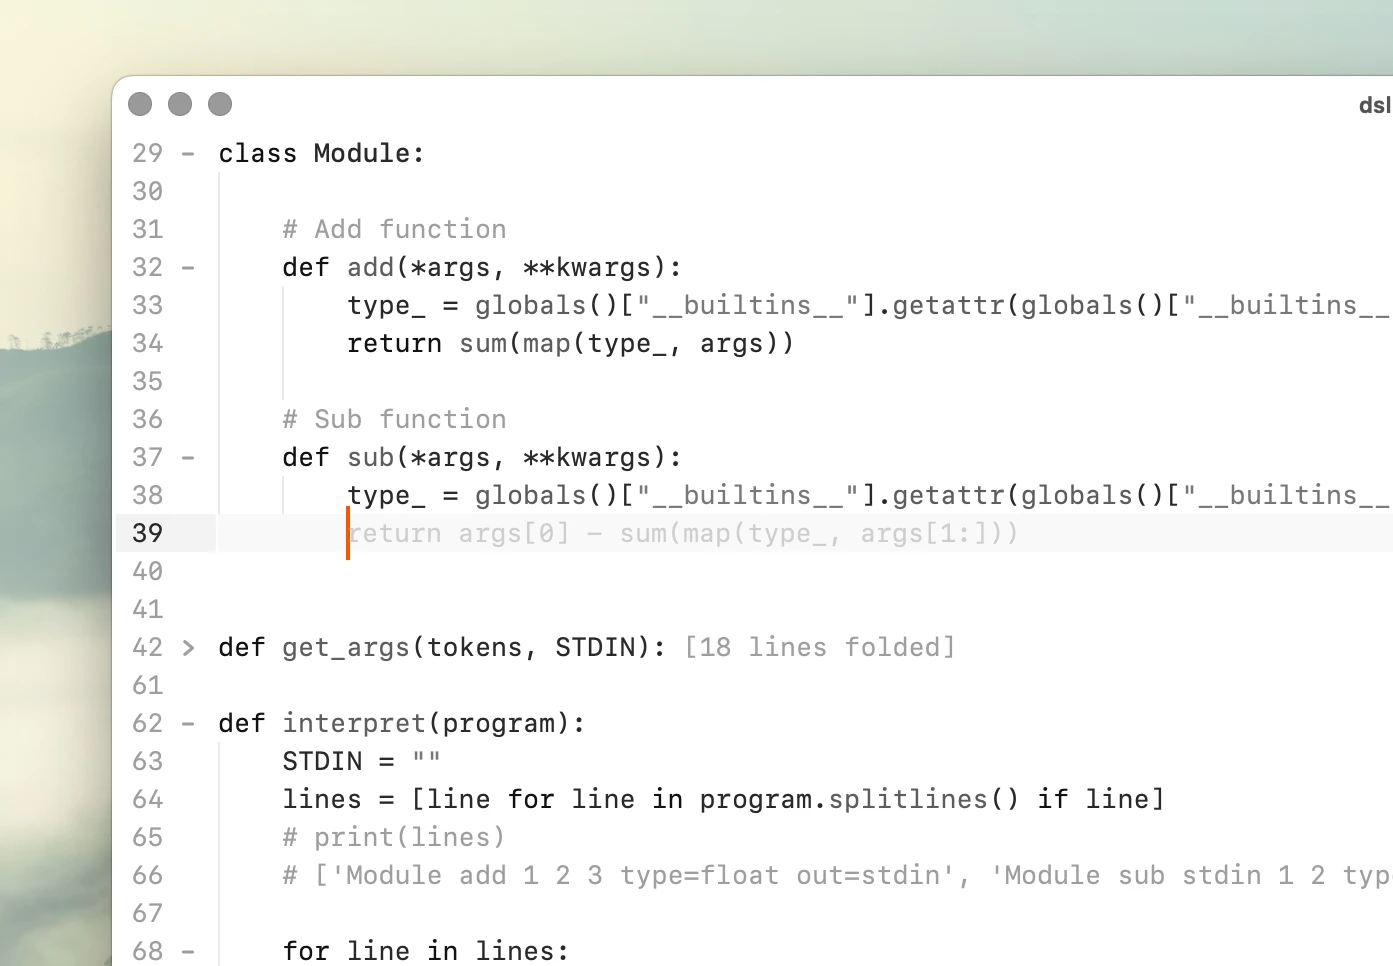
Get inline code suggestions while you type, powered by a local model through [Ollama](https://ollama.com).
Completions appear as ghost text in the editor and only become part of the document when you accept them.
## How it works
Koi generates completions while you type or after starting a new line.
A small amount of code before and after the cursor is sent to the configured completion model.
Koi uses this context to generate a suggestion for the remainder of the current line.
[Why only complete the current line?](#why-only-complete-the-current-line)
The context is deliberately kept small.
Larger contexts can give the model more information, but they also take longer to process.
For something that runs while you type, keeping latency low is more important than giving the model an entire project.
### Fill-in-the-middle
Code completion works best with models that support fill-in-the-middle (FIM) generation.
FIM models use code on both sides of the cursor when generating a completion.
This makes them particularly useful when editing existing code, where what comes after the cursor can be just as relevant as what comes before it.
## Accepting completions
Suggestions are displayed as ghost text and do not modify the document until you accept them.
| Action | Description |
|:--------------------------------------------------------------|:--------------------------------------------------|
| ⇥tab | Accept the current code completion. |
If no completion is visible, Tab continues to work normally.
The command used to accept completions can be changed in the configuration:
accept_code_completion
The value is an editor command rather than a key combination.
This allows completion acceptance to share an existing command without taking over its normal behavior.
accept_code_completion
With the default bindings for `move_caret_line_end`, ⌘→ or ⌃E will accept a visible completion.
When there is no completion, the command simply moves the cursor to the end of the line as usual.
Continue typing or move the cursor and the current suggestion disappears.
## Local models with Ollama
Code completion runs locally through [Ollama](https://ollama.com).
Install Ollama and choose a coding model from the [Ollama model library](https://ollama.com/search).
A model with fill-in-the-middle support is recommended.
Small coding models are often a good fit for inline completion because they can generate suggestions quickly on local hardware.
Larger models may produce better predictions, but usually at the cost of higher latency.
For example, to use a local model:
`ollama pull qwen2.5-coder:1.5b`
List the models available through Ollama:
`ollama list`
You can also run the command from Koi's inline shell:
% ollama list
NAME                     ID              SIZE
qwen2.5-coder:1.5b       6d3abb8d2d53    986 MB
Use the name from the `NAME` column in your Koi configuration.
Koi sends completion requests directly to the Ollama instance configured on your machine.
Koi does not require a cloud AI service or account for code completion.
### Configuration
Open the Koi configuration file with:
| Action | Description |
|:--------------------------------------------------------------|:--------------------------------------------------|
| ⌘command , | Open the configuration file. |
Navigate to the models section and add your completion model:
code_completion
The value should match the model name reported by `ollama list`.
#### Disable code completion
To disable code completion, remove or comment out the setting:
When no completion model is configured, Koi does not make completion requests.
This is the default.
## Why only complete the current line?
Koi generates current-line completions rather than automatically suggesting large blocks of code.
It deliberately does not do next edit prediction or move the cursor to arbitrary positions in the editor.
Short suggestions are faster to generate, easier to evaluate, and less disruptive while editing.
Limiting completion to the current line also keeps each suggestion small and predictable.
Most importantly, a completion remains only a suggestion until you accept it.
The aim is to make code completion part of normal editing rather than something that takes over the editor.